[ez-toc]
A speech-to-text API lets a program send audio to a transcription service and receive text back, instead of a person uploading a file through a website. The workflow is the same idea as uploading a recording, but it is done with code: prepare the audio, send it with an API key, wait for the job or stream the result, and then handle the transcript, timestamps, and errors in your own system. This guide explains that workflow step by step. It is not a ranking of services. For a comparison of services, see our guide to the best AI transcription APIs for developers.
You do not need to be an expert programmer to follow this guide, but you do need to be comfortable running code or working with a developer. The examples use plain language and describe the requests in words, with one short code example from official documentation to show the shape of a request. The exact endpoint names, limits, and model names differ between providers and change over time, so always check the provider’s current documentation before you build on it.
What a Speech-to-Text API Does
A transcription API, also called a speech-to-text API, accepts audio and returns a transcript. Most APIs offer two modes. In file mode, you upload a completed recording and receive a finished transcript, sometimes in stages as the file is processed. In streaming or real-time mode, you send audio as it is being recorded, such as from a microphone or a phone call, and receive text in near real time. File mode suits recordings, meetings, and interviews. Streaming mode suits live captions, call handling, and any case where the text is needed while the person is still speaking.
Most APIs return more than plain text. Common outputs include word or segment timestamps, confidence scores, speaker labels, language detection, and subtitle formats such as SRT or VTT. Some also return alternative word choices for uncertain passages. Your code decides what to keep: for a searchable archive, keep the full transcript with timestamps; for captions, keep the timed segments; for a meeting summary, keep the speaker-labelled text and discard low-confidence alternatives after a human check.
Step 1: Prepare the Audio Before You Send It
Prepare the audio the same way you would for any transcription: a clean recording, the right language, and a format the API accepts. Check the provider’s list of accepted formats, which commonly includes MP3, MP4, M4A, WAV, and WebM, and check the file size limit. One widely used API, for example, accepts files up to 25 MB for a single request, so larger recordings must be split or compressed. The same format and quality checks that apply to manual uploads apply here, including the checks in our guide on how to transcribe MP4 files to text.
Split long recordings at natural breaks, such as pauses between speakers or topics, not in the middle of a sentence, because splitting mid-sentence removes context and reduces accuracy. Keep the original file, and give each chunk a clear name that records its order, so the finished segments can be joined in the right sequence. If the recording has several speakers, note their names and the order in which they speak, because that note helps whoever checks the speaker labels later.
Step 2: Authenticate With an API Key
Every transcription API needs authentication, usually an API key sent in the request header. Create the key in the provider’s dashboard, keep it secret, and never put it in a public web page, a shared document, or a code repository. If a key is ever exposed, revoke it and create a new one. For a first test, use a short, non-sensitive recording, so a mistake in the request does not send private audio to the service. Check the provider’s privacy terms before you send real recordings, and confirm how long audio and transcripts are stored.
Set the language and any extra options in the request. Common options include the expected language or languages, whether to include word timestamps, whether to label speakers, and a prompt or keyword list with names and technical terms that should be recognised. A prompt with expected terms helps with proper nouns, but it is a hint, not a guarantee: the API may still mishear a term, and it can in rare cases insert a prompted term that was not spoken. Check prompted terms against the audio, just as you would check any other name.
Step 3: Send the Audio and Handle the Job
For file transcription, send the audio file in one request and receive either the transcript or a job identifier. If you receive a job identifier, poll the job status until it is complete, failed, or timed out, and handle each case in code: save the transcript when it succeeds, log the error when it fails, and retry only a failed job, not a job that is still running. Do not poll in a tight loop; wait between checks, and set a maximum wait time so a stuck job does not block your system.
A typical file request looks like the example in the OpenAI speech-to-text documentation, which sends an audio file to the transcriptions endpoint with a model name and returns the transcript text. The shape is the same across providers: an audio file, a model or language choice, and optional settings, sent with authentication. Your code should read the response, check the status code, and store the transcript with the job identifier and the original file name, so any later problem can be traced back to the right recording.
Step 4: Work With Timestamps, Speakers, and Formats
Once the transcript arrives, decide which output format you need. For captions, request or convert to SRT or VTT with timed segments, and check the timing against the video before publishing. For editing, keep word timestamps so an editor can click a word and hear that exact moment. For speaker-labelled text, keep the segment start and end times with each speaker label, and check the labels at speaker changes, as explained in our guide to speaker diarization. For a readable document, use sentence timestamps and paragraph breaks, and add headings at topic changes.
Timestamps are also how you keep a transcript useful after the API call ends. Our guide on adding timestamps to a transcript explains how timestamp formats work and how to check them. If your API returns timestamps in seconds, convert them consistently to the format your player or editor expects, and test one file end to end before you process a batch, because a one-second offset in every segment is easy to miss in a long transcript.
Step 5: Streaming Mode for Live Audio
Streaming mode sends audio in small chunks while the recording is still happening, and the API returns partial results that are later revised into final results. Your code must handle both: show partial text as provisional, replace it when the final text arrives, and do not treat a partial result as finished. A partial result may change as more context arrives, so a word shown live can be corrected seconds later. This is normal for streaming speech recognition, and it is why live captions sometimes show a word that then changes.
For streaming, keep the connection open, send audio steadily, and handle reconnections. If the connection drops, your code should reconnect and, where the API supports it, resume from the last final result rather than restarting from the beginning. Test streaming with a real microphone and a real call, not only with a file played back, because network delay, echo, and background noise in a live setting behave differently from a clean file.
Errors, Limits, and Costs to Plan For
Plan for the API’s limits before you depend on it. Common limits include file size, audio length, requests per minute, and concurrent jobs. When a limit is hit, the API returns an error, and your code should wait and retry with a delay, not retry immediately in a loop. Log every error with the job identifier, the file name, and the time, so a failed batch can be re-run without re-sending files that already succeeded. For costs, most APIs charge by audio duration, so a two-hour recording costs roughly twice a one-hour recording, and streaming charges for the time the connection is open, not only for speech.
Accuracy limits are the same as for any AI transcription: noise, overlap, accents, and specialist vocabulary cause errors, and the API will not flag every error. Build a human check into the workflow for any transcript that will be published, quoted, or used as a record. The Google Cloud Speech-to-Text documentation describes the same service shape, sending audio and receiving a text transcription from the API, and it is a useful second reference for how request options and limits are documented. Use the API for speed and scale, and use a human editor for the final check.
How This Guide Differs From the Best-API Comparison
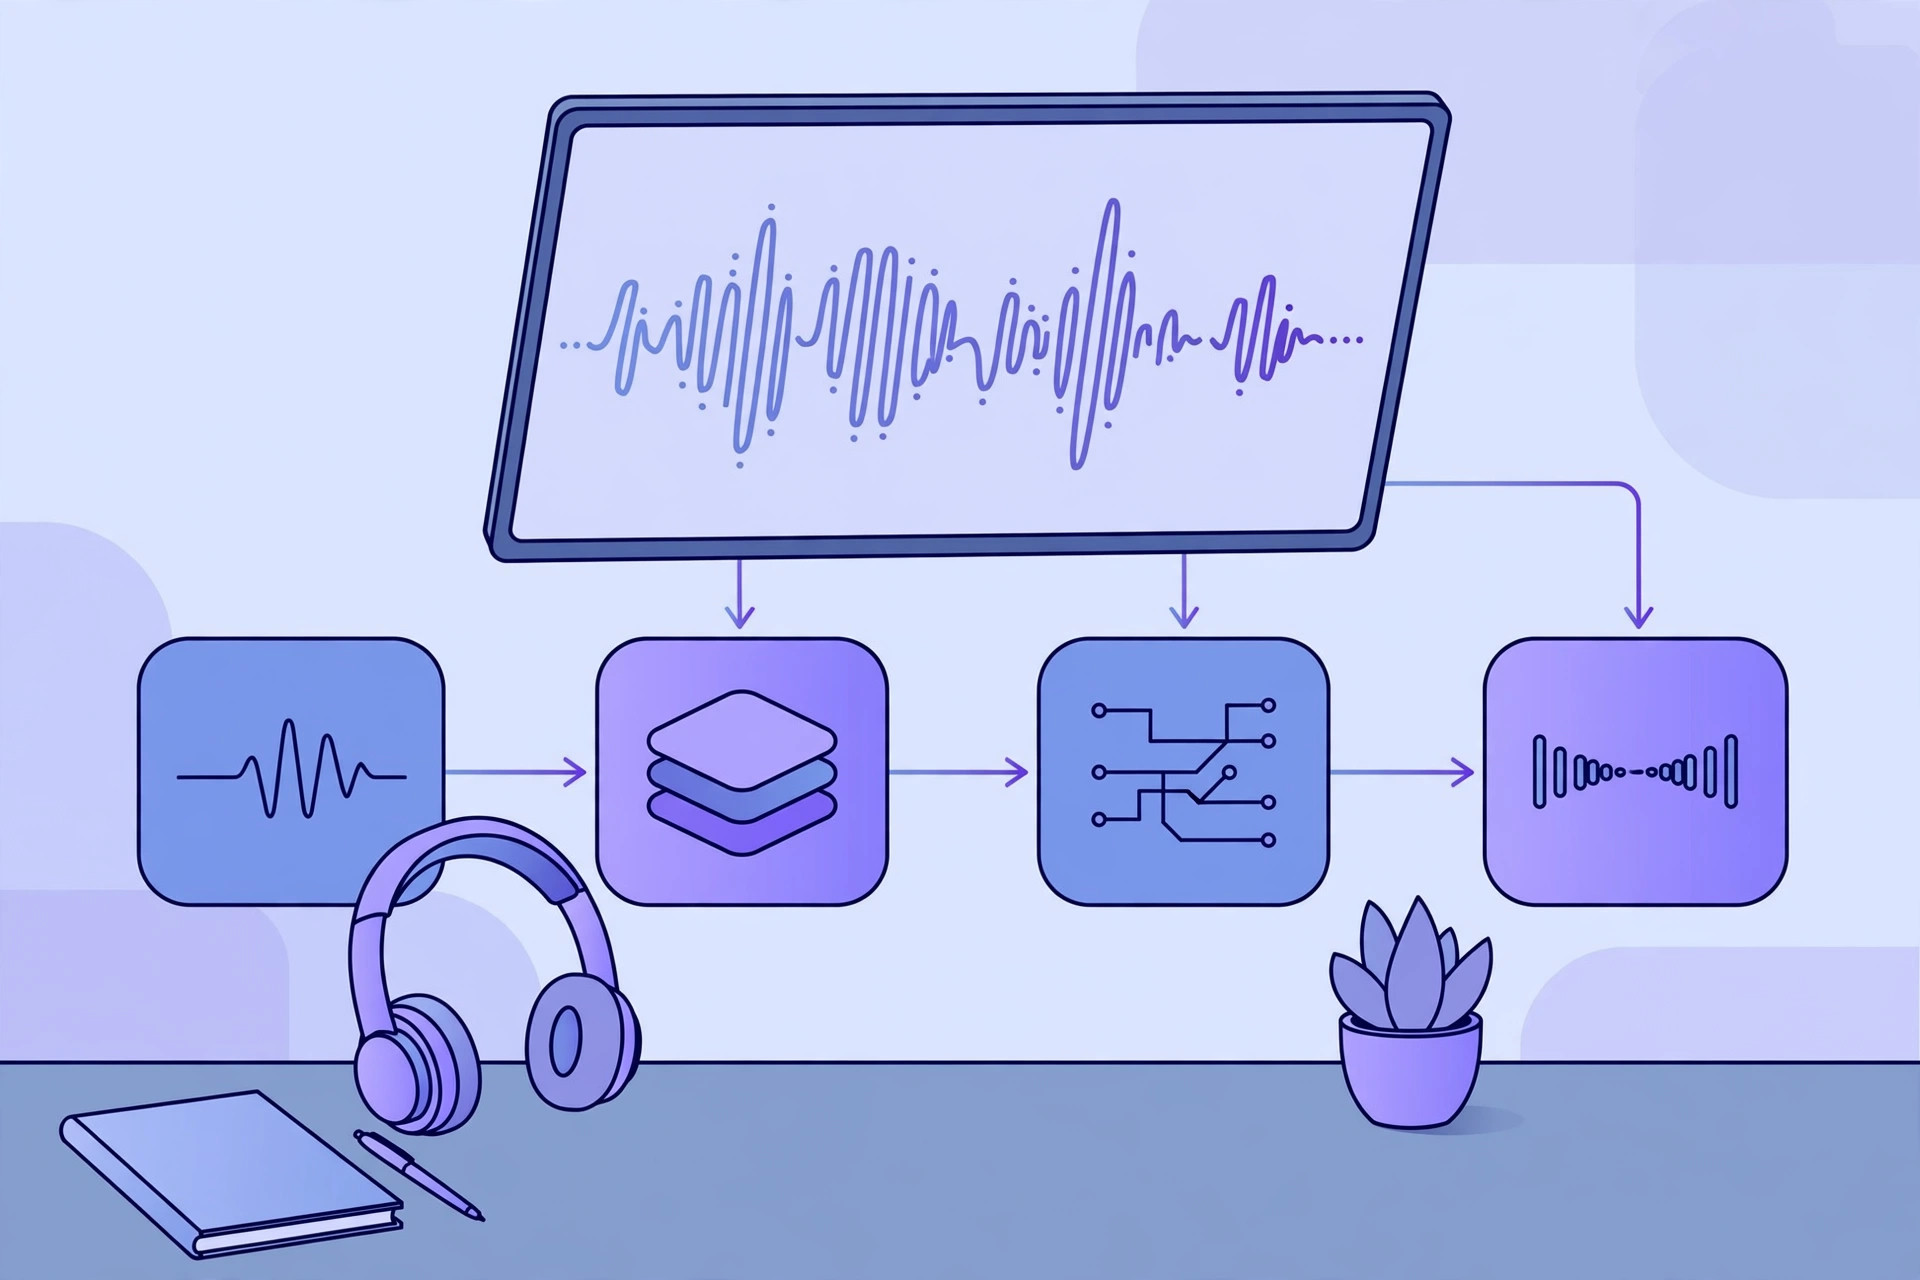
This guide describes a workflow that works with any provider. It does not rank providers, compare prices, or recommend one service over another. If you have not chosen a provider yet, read our comparison of the best AI transcription APIs for developers first, choose one that fits your language, format, and privacy needs, and then return here to build the workflow. If you already use a provider, the steps here apply directly, with the provider’s current endpoint names and limits taken from its own documentation. For the technology behind the API, including how speech recognition models turn sound into words, see our guide on how AI transcription works.
Conclusion
Using a speech-to-text API means preparing the audio, authenticating with a key, sending the file or stream, handling the job and its errors, and then working with timestamps, speakers, and formats in your own system. Keep the original audio, log every job, check names and numbers against the recording, and test one file end to end before you process a batch. That workflow gives you the scale of an API without losing the accuracy check that a transcript used as a record always needs.
Do I need to know how to code to use a speech-to-text API?
Yes, in most cases. An API is used from code or from a tool that calls the API for you. If you do not write code, use a transcription tool with a website upload instead, or work with a developer for the API setup.
What audio formats do speech-to-text APIs accept?
Most accept MP3, MP4, M4A, WAV, and WebM, with a file size limit per request. Always check the provider’s current list, because formats and limits change.
Can an API transcribe live audio?
Yes, through streaming mode, which sends audio as it is recorded and returns partial results that are later revised. Handle partial and final results separately in your code, and test with a real microphone before going live.
Limitations & Edge Cases
- Audio that does not meet the provider’s format, sample-rate, or size requirements may be rejected outright or transcribed with degraded quality. Confirm the accepted formats in the provider’s documentation before sending your first file.
- Costs and processing time scale with audio length, and long jobs need polling, retries, and timeout handling. A design that works for a one-minute test clip can fail quietly on an hour-long recording.
- Without a custom vocabulary, names, product terms, and jargon are routinely misheard. If your audio is full of proper nouns, plan for a vocabulary list or a manual correction pass.
- Audio sent to an API leaves your machine. Before sending sensitive recordings, read the provider’s retention and privacy terms and confirm how long files and transcripts are kept.
Test with your most difficult realistic sample — noisy, accented, multi-speaker — before wiring the API into anything that other people depend on.
Do I need to know how to code to use a speech-to-text API?
Yes, in most cases. An API is used from code or from a tool that calls the API for you. If you do not write code, use a transcription tool with a website upload instead, or work with a developer for the API setup.
What audio formats do speech-to-text APIs accept?
Most accept MP3, MP4, M4A, WAV, and WebM, with a file size limit per request. Always check the provider’s current list, because formats and limits change.
Can an API transcribe live audio?
Yes, through streaming mode, which sends audio as it is recorded and returns partial results that are later revised. Handle partial and final results separately in your code, and test with a real microphone before going live.
How do I authenticate with a speech-to-text API?
Every transcription API needs authentication, usually an API key sent in the request header. Create the key in the provider’s dashboard, keep it secret, and never put it in a public web page, a shared document, or a code repository. If a key is ever exposed, revoke it and create a new one.
What should I do when I send audio for file transcription?
Send the audio file in one request and receive either the transcript or a job identifier. If you receive a job identifier, poll the job status until it is complete, failed, or timed out, and handle each case in code: save the transcript when it succeeds, log the error when it fails, and retry only a failed job, not a job that is still running. Do not poll in a tight loop; wait between checks, and set a maximum wait time.